


Article
What Is Ollama? Running a Local LLM, and Why I Moved to Claude

I have been writing about AI since early 2023. Over that time, I have watched it change how I code, how I think about content, and how I think about the future of work.
This is a story about going one level deeper, from using artificial intelligence as a tool to trying to build something autonomous on top of it. It did not work the way I expected.
WHAT IS A LOCAL LLM, AND WHAT IS OLLAMA?
A local LLM is a large language model that runs on your own hardware instead of a provider's servers, so your data never leaves the machine and there are no per-request fees. Ollama is the open-source tool I used to do this on a Mac Mini: you pull a model with a single command and it runs locally behind a simple API. Getting it running took minutes.
Running AI locally is genuinely easy to start and genuinely hard to make useful for real work. The setup was not the problem. The limit was the context window, and that is the part nobody mentions until they hit it. Here is what actually happened when I pointed a local model at production data.
WHY I TRIED RUNNING AI LOCALLY
Before I had any real experience with it, local AI seemed like the most interesting move I could make. Not just because of flexibility or security, although both mattered, but because it felt like the most honest way to approach the technology.
In the middle of everything happening around AI, actually running a model locally, configuring it, connecting it to data, and seeing where it breaks felt fundamentally different from using a polished cloud interface. It felt like the difference between using a tool and understanding how that tool actually works.
That difference comes down to visibility. A cloud interface stays polished by keeping the mechanics out of sight: the system prompt, the training, the way it weighs one token against the next. Running a model myself was the only way to see any of that, and it is a gap I wrote about separately in what a cloud AI model hides from you.
At the same time, I was not approaching it as a purely technical experiment. I had a clear use case in mind from the beginning.
The first area I wanted to apply this to was SEO. SEO is a documented, relatively exact discipline. It has structure, rules, patterns, and measurable outcomes. In theory, that makes it ideal for automation. An agent can scan hundreds of subpages in minutes, identify structural issues, detect missing elements, and if it also has access to search trend data, it can produce meaningful content recommendations.
That is not an abstract idea. That is a real workflow with clear business value.
The broader vision was more ambitious. I wanted to build an agent that retrieves data based on configured automations, proposes steps based on what it finds, sends those proposals somewhere for review, and through that feedback loop gradually improves. At a certain point, once its proposed steps consistently match what I consider good decisions, it would start executing those actions autonomously.
Not just assisting. Acting.
That was the goal.
HOW TO RUN AN LLM LOCALLY: MAC MINI, OLLAMA, N8N
The setup itself was straightforward. I used a Mac Mini, ran a local model through Ollama, and handled basic orchestration via n8n.
Getting Ollama running was surprisingly simple. Much simpler than I expected. Within a short time, I had a model up, responding, and behaving like a chatbot. From a purely technical perspective, the barrier to entry was low.
Within a few hours, I had a basic pipeline in place. The model was able to retrieve data, run a basic marketing analysis, and I had a clear path toward automating alerts into Slack based on the output. At that stage, everything felt promising. The system was working, and it was working locally.
What I did not yet fully understand was how quickly I would run into its limits.
Then I tested it on representative sample data designed to simulate real-world conditions.
THE CONTEXT WINDOW
This is where the real limitation became obvious.
The model could handle a few pages of text. It could process a small table, or a dataset with a size of a few kilobytes. Within that range, it behaved in a way that looked functional.
But the moment I gave it representative SEO data, the kind of volume you actually need to analyse if you want meaningful output, the system broke down.
It processed what fit into its context window and ignored the rest. It produced output that, on the surface, looked structured, but when you looked closer, it had almost no value. It would pick up a number somewhere in the data and repeat it back. It did not combine signals. It did not prioritise correctly. It did not understand relationships across the dataset.
And the reason was simple. It could not see enough of it.
I noticed this immediately during the first real analysis. The quality of the output was roughly comparable to what cloud models were producing in 2023. That is not a criticism of the model itself. It is a reflection of the constraints.
The problem was not configuration. It was not prompting. It was not lack of effort.
The hardware determined which model I could run. And the model I could run simply could not hold the amount of information required for the task.
WHAT AUTONOMOUS ACTUALLY MEANS
At this point, it became clear what "autonomous" actually requires in practice, and where the system was falling short.
An autonomous agent is not just a loop that calls a model repeatedly. It requires the ability to reason across a large amount of context, maintain coherence across multiple steps, and produce outputs that are precise enough to act on without constant supervision.
That means it needs to hold not just the current input, but the accumulated state of the entire workflow. What data was retrieved, what actions were proposed, what decisions were made, what failed, what succeeded, and what the overall objective is.
This is where the limitation becomes structural.
A model with a constrained context window cannot maintain that state. It cannot connect decisions across time. It cannot evaluate its own outputs in a meaningful way because it lacks visibility into the full process.
The vision of the system was not the problem.
The infrastructure underneath it was.
SWITCHING TO CLAUDE CODE
At that point, I moved to a cloud-based solution and started working with Claude Code from Anthropic.
Join the Library
Full access to my findings, personal stories, and what I learn from the people I meet.
Join the Library · €29.99 per year How a small business, creator or politician can be… What should I study in the age of AI?… I Left My Job for Several Months to Read… How I Fell in Love With Her, at First… How do you stop depending on social media? Can… How to Start With AI in a Company: Automating…Get the full article by email and feel free to reply if you want to discuss it further.
Summary
Common questions on this article's topic
What is the difference between running AI locally and using cloud AI?
What is a context window and why does it matter?
What is Ollama and how easy is it to set up?
Can local AI models handle real business data analysis?
What is an autonomous AI agent?
Should developers start with local AI or cloud AI?
Can a local LLM be as good as ChatGPT?
If you have any thoughts, questions, or feedback, feel free to drop me a message at mail@richardgolian.com.
 LinkedIn


Related articles
In April, in the first part of this series, I wrote about an AI prediction system I had started building on my own machine. At the time the software was a few hours old and the prediction record was empty. The record since then has shown one thing: the system does not yet understand the market it is being asked to forecast. It can pull macro context, book value, earnings. But it cannot put those together into something that helps it understand the price.
I am building an AI system to predict the S&P 500. It runs on my own machine, uses free public data (yfinance, FRED, the Shiller dataset), and grades every forecast against reality. This series documents the build itself: the decisions, the methodology, the mistakes. What I will eventually share from the running system is a separate question, and an honest one.
Yesterday I could not tear myself away from the computer. When I lifted my head, it was half past eight in the evening. I had been sitting alone upstairs for about three hours.
More articles
Are you a content creator playing by the rules of YouTube, Instagram or Google? Are you a small business owner whose business model depends on how often Amazon recommends you, how expensive Facebook ad impressions will be or how expensive Google Ads clicks will be? If all or most of your contact with your audience or customers depends on a big platform showing you to them, you are not in a strong position.
The development of artificial intelligence changes how we look at which paths in life make sense. Which studies and which profession to choose.
It was Thursday, 31 March 2022, when I handed over the last of my responsibilities to my colleagues, closed my laptop and went to the library. I left my job for several months and immersed myself in philosophy. And I am immensely grateful for it. Today I am, like most people, on a merry-go-round, and it is hard for me to stop and think about the fundamental questions of my own life.
It was September 2023. My life, my work, everything was completely different from now. It was simpler. I owned almost nothing. I needed to film an advert, I went up to a floor inside the company where the product I needed for that advert was, and there I noticed her for the first time. She laughs at me when I describe it like this, but at that moment the universe told me, that is her.
How and why I am gradually leaving social media and the big platforms. When I read that Meta is testing a new way to charge for organic posts that link outside its platform, it confirms how right I was to become steadily less dependent on the big platforms and on social media. It does not mean I have left them completely. It means that whether or not I stay in touch with my readers depends on them less and less, and today almost not at all.
One of my family members described a firm that has its data in several different tools, and its employees still join it by hand, in spreadsheets. That is the ordinary state of firms. When somebody tells such people not to do it by hand and to use AI, they will not understand. Most firms do not even have the basic connectors between the tools they use. These firms need help with AI transformation.
The same task, two models. Fable 5 against Opus 4.8. On paper Fable is the better model, with a larger context and stronger specs. And still it lost. Opus handled the task with a single round of checking for 721,000 tokens, while Fable needed nine rounds and burnt through 2.78 million tokens. The difference was not in the model, but in how I set the task. And I know it, because I measured it.
A few weeks ago I installed a small local AI model on my laptop that watches a live camera feed. I turned the webcam on in the dark, and in near total darkness it recognised me and the objects in the room. That such things exist, I have known for a long time. What opened my eyes was the accessibility. I installed it in one prompt, free, and it runs entirely on my machine, sending data nowhere.
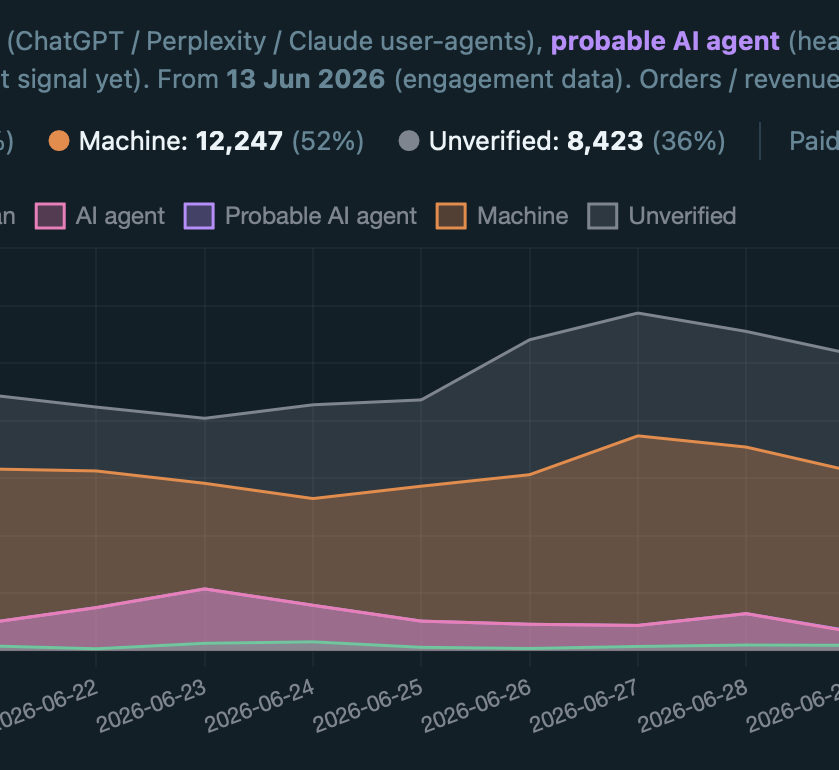
I once wrote about building my own privacy-friendly analytics tool. It had bot detection from the first version, yet it was not enough. Direct visits took a strangely high share of my traffic. When someone claims that 20% of their visits are bots and 80% are humans, I used to think the same. Today I would say the opposite ratio is closer to the truth. This is how I got there.
I have Heidegger and my notebook beside me. I am asking where all of this is heading, where artificial intelligence is taking us.
Four days in Catalonia. No computer, no AI, almost no social media. I bought this notebook so that I could write down what I would think about, and what I would come across and learn on the trip.